What Agents Lack Isn't a Smarter Model—It's an Understanding of the Business
AI agents often fail in the enterprise not because they cannot reason, but because they lack business knowledge. Neo4j's Context Engine organizes processes, terminology, data location, permissions, and past decisions into a six-layer ontology and graph, combining GraphRAG retrieval with memory and learning. This article explains the approach and the questions that remain in private preview.

What Agents Lack Isn't a Smarter Model—It's an Understanding of the Business
When an AI agent pulls an account record and sees a status of "2," it most likely has no idea that this means "suspended pending review." The engineer who wrote the code knows. The experienced employee knows—maybe because someone wrote it on a sticky note, maybe because it shows up in a BI report. But the agent cannot reach that context.
Neo4j's newly announced Context Engine, part of the Neo4j Graph Intelligence Platform, is aimed squarely at this gap. The question it asks is not "can the model reason?" but "does the agent know what the company's words mean, how its processes run, where its data lives, and what it is allowed to touch?" Neo4j calls this the agent knowledge problem and describes it as a "trillion-dollar AI bottleneck": if agents do not understand how an organization works, they cannot act reliably at scale.
That framing deserves serious attention, because it moves the conversation from model capability back to knowledge engineering.
Agents Are a New Kind of Data Consumer
For decades, data had two kinds of consumers: applications and people. Meaning therefore lived in two places—in code and in human memory. An application knows that account status "2" means "suspended pending review" because the rule is written in code. A person knows because of experience, because they wrote it on a sticky note, or because they saw it in a BI tool.
Agents have neither. They can see the field, but not the convention behind it.
The harder problem is that the same word can mean different things in different parts of the same company. "Customer" may refer to one group in Marketing and a different group in Finance. On top of that, data is scattered across clouds, platforms, and vendors, so agents often do not even know where to look. Ambiguous meaning, conflicting definitions, and fragmented data stack into the obstacle that is hardest to avoid when putting agents into production.
A Six-Layer Ontology: Breaking "Understanding the Business" into Something You Can Model
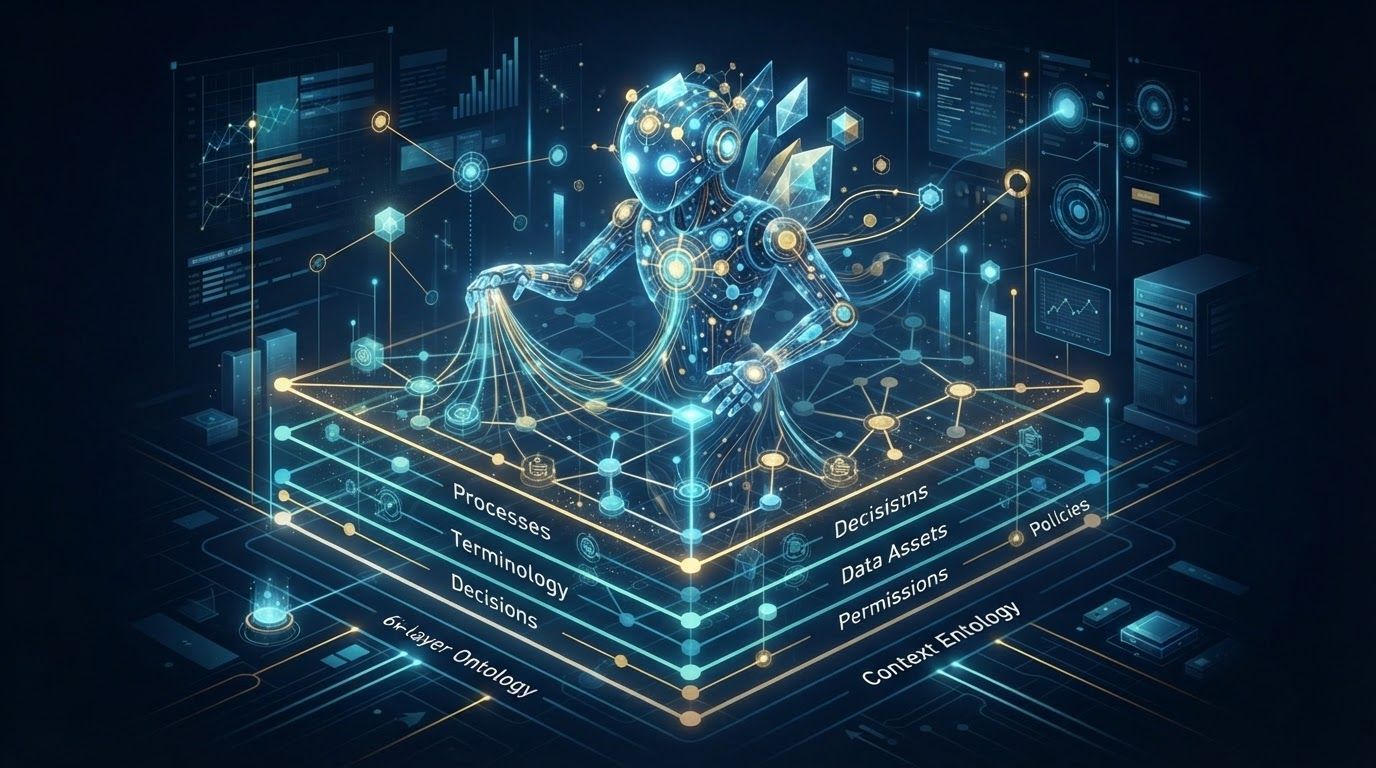
Neo4j's answer is an interconnected six-layer business ontology. It takes a phrase as vague as "understand the business" and breaks it into layers that can be defined and governed one by one.
The first two layers handle understanding:
- Business process and organization: describes how the organization operates, including its rules and processes.
- Domain ontology: defines key terms and concepts so agents know what specialized vocabulary means.
The middle three layers handle connection:
- Data products: determines what information may be used.
- Physical systems: determines where that information actually lives.
- Tools and integration: determines how to connect to it and in what form to access it.
The final layer handles learning:
- Runtime knowledge: lets agents remember past decisions and actions and build experience from them.
These three capabilities map to understanding the business, finding the data, and learning continuously. Putting them in the same graph is what lets an agent know who "customer" refers to, which system to query, what it can do with the result, and what its actions left behind.
Three Components, Three Capabilities
Context Engine consists of three core components, one for each of those capabilities.
Business Ontology for Agents is a graph model that an enterprise defines, stores, and enforces in Neo4j. It captures what business concepts mean, how processes work, and how concepts and processes relate to one another. Agents use it to understand the nature of questions and tasks, including highly complex ones.
Context Build and Runtime addresses where data lives and whether it can be used. It lets agents reach the information they need across clouds, platforms, and vendors, with built-in governance that ensures they can access only data they are authorized to access. For retrieval it uses GraphRAG rather than vector-only search. Neo4j claims GraphRAG is more accurate and more cost-effective than vector-only RAG.
Memory and Learning is what makes agents improve with use—critical in a constantly shifting enterprise environment. Short-term, long-term, and reasoning memory sit in the same graph as business meaning, and every decision and decision path is tracked and stored. The material an agent learns from is therefore not a summary generated out of thin air, but the path it actually took.
Graph Structure Buys More Than Retrieval
Modeling relationships explicitly is the most fundamental difference between this approach and "chunk the documents, then run vector search." Once relationships become edges in a graph, an agent can reason along them and, when needed, explain how it reached an answer. In enterprise settings, that explainability and traceability often matter more than getting one more question right.
There is a practical advantage, too: enterprises do not have to replace their existing LLM or agent framework. What Context Engine provides is a context and knowledge layer, not another development platform to migrate onto. The accompanying Context Studio pulls ontology management and governance into a single control plane, reducing the complexity of long-term maintenance.
The Boundary: What Ships Today and What Still Needs Proof
To be clear, Context Engine is currently in private preview, and enterprises have to join as design partners. Most of the capabilities described above have not yet been broadly tested in large-scale production.
At least three questions are worth asking during an evaluation. First, GraphRAG's accuracy and cost advantage over pure vector search is currently a vendor claim and needs to be tested against a company's own data. Second, whether governance truly ensures that agents "can only access data they're authorized to access" depends on how deeply it integrates with existing permission systems. Third, the six-layer ontology is not something you configure; it is a knowledge asset that business, data, and platform teams must build and maintain together. That investment is often much larger than adopting a retrieval service.
Reliable Agents Are, Ultimately, a Knowledge Problem
Conversations about agents drift easily toward model parameters, context windows, and reasoning techniques. But what actually stalls enterprises is usually a plainer problem: the agent does not know what "2" means, who "customer" refers to, or which system holds the data.
The value proposition of Neo4j Context Engine is to gather the conventions scattered across code, sticky notes, reports, and human experience into a single graph that can be governed, reasoned over, and traced. Whether that direction holds depends on whether enterprises are willing to treat business meaning as a long-term asset. Models will keep getting stronger, but the meaning of the business will not become clear on its own.